

Dataset
MNIST Test Labels (10K)
10,000 test labels (0-9) corresponding to the test images.
—Records
4.4 KBFile size
GZIPDelivery formats
—Data updated
A classic handwritten digit dataset created by Yann LeCun and others in 1998. Seventy thousand 28x28 grayscale images covering the ten digit categories from 0 to 9—almost the starting point for all deep learning courses and tutorials.
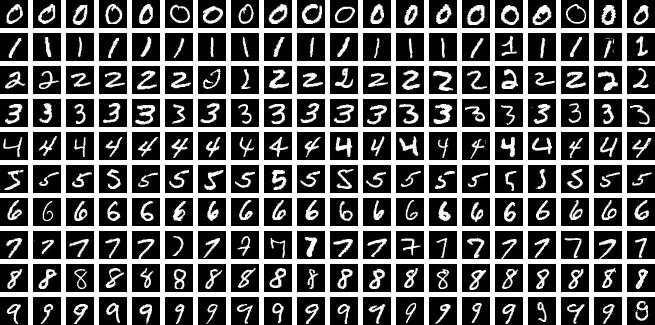
After more than twenty years of validation, MNIST remains the benchmark of choice for entering machine learning and evaluating new algorithms.
As the most classic benchmark dataset in the field of machine learning, it has been cited by tens of thousands of papers. Almost all classification algorithms, including SVM, CNN, and Transformer, have validated their performance on MNIST.
The sample distribution of the 10 digit categories (0-9) is uniform, and both the training and testing sets are carefully divided, allowing direct use for model training without additional data balancing processing.
All images have been standardized—normalized to 28x28 pixels, centered, and grayscaled. Ready to use, with no complex data cleaning and preprocessing pipeline required.
Compressed to about 11 MB, and less than 50 MB when uncompressed. Any laptop can complete model training in a few minutes—no GPU or cloud computing power needed.
With over 25 years of academic accumulation, it has the richest reference implementations, tutorials, and paper libraries. Any issues encountered can find ready-made answers and best practices.
Uses the Creative Commons Attribution-ShareAlike 3.0 license. Freely usable for academic research, commercial projects, and educational purposes, with proper attribution required.
From classroom teaching to cutting-edge research, MNIST is a bridge connecting theory and practice
Build an end-to-end image classification pipeline—complete introductory practice of data loading, feature extraction, model training, and metric evaluation
The best hands-on experimental platform to understand core concepts such as backpropagation, activation functions, loss functions, and optimizers
Validate the performance of convolutional neural network architectures—from LeNet-5 to the latest lightweight models, tracking the technological evolution in computer vision
The first practical project in almost all deep learning courses worldwide—helping students build and train their first model from scratch in just a few hours
MNIST dataset uses IDX binary file format:
Training images: train-images-idx3-ubyte (60,000 images)
Training labels: train-labels-idx1-ubyte (60,000 labels)
Test images: t10k-images-idx3-ubyte  (10,000 images)
Test labels: t10k-labels-idx1-ubyte  (10,000 labels)
Image file header structure (16 bytes):
┌──────────────┬──────────────────────┐
│ Offset       │ Description          │
├──────────────┼──────────────────────┤
│ 0000         │ Magic Number (2051)  │
│ 0004         │ Number of Images     │
│ 0008         │ Number of Rows (28)  │
│ 0012         │ Number of Columns (28)│
└──────────────┴──────────────────────┘
Each image: 784 bytes (28 × 28)
Pixel value range: 0 (white) ~ 255 (black)
MNIST uses a compact and efficient IDX binary format to store image and label data, which is natively supported by mainstream deep learning frameworks.
4 Files — The training and test sets each contain one image file and one label file, distributed in gzip compressed format.
Pixel-wise Storage — Each image is stored as 784 bytes in row-major order, with labels as single-byte unsigned integers from 0-9.
Native Framework Support — PyTorch (torchvision.datasets.MNIST), TensorFlow (tf.keras.datasets.mnist), etc., can automatically download and parse with a single line of code.
From browsing to training, just a few minutes
View detailed information, sample previews, and data distribution of the MNIST dataset on the platform to gain a comprehensive understanding of the dataset features.
Obtain the standardized IDX format data files. The compressed package is only about 11 MB, and you can start using it after downloading.
Use frameworks like PyTorch, TensorFlow, or scikit-learn to load the data with a single line of code and start training your first image classification model.
MNIST is the first step for millions of developers into deep learning. Get the dataset and train your first model.